

GPT-6 Luna
Ship gives you the highest intelligence per dollar of any frontier model by finding the cheapest execution that still meets a model's quality grade. We first introduced it for Claude Opus 4.8 and GPT 5.6 Sol. Today we're adding GPT-6 Luna with the same quality SLA, the same cost reduction, and the same ease of use.
Just name a reference model as a quality grade, and we fulfill each request in the cheapest way that still meets that grade. We measure both Capability Equivalence and Behavioral Equivalence to the reference model, so that the model performs as well as expected, and it works the same way within your harness when you switch to ship.
TL;DR. Changemodel="openai/gpt-6-luna"tomodel="ship-like/gpt-6-luna". Same answers, for at least 50% less (in our evals, 52.3% lower) with a quality SLA.
New to Ship? Start with Introducing Ship.
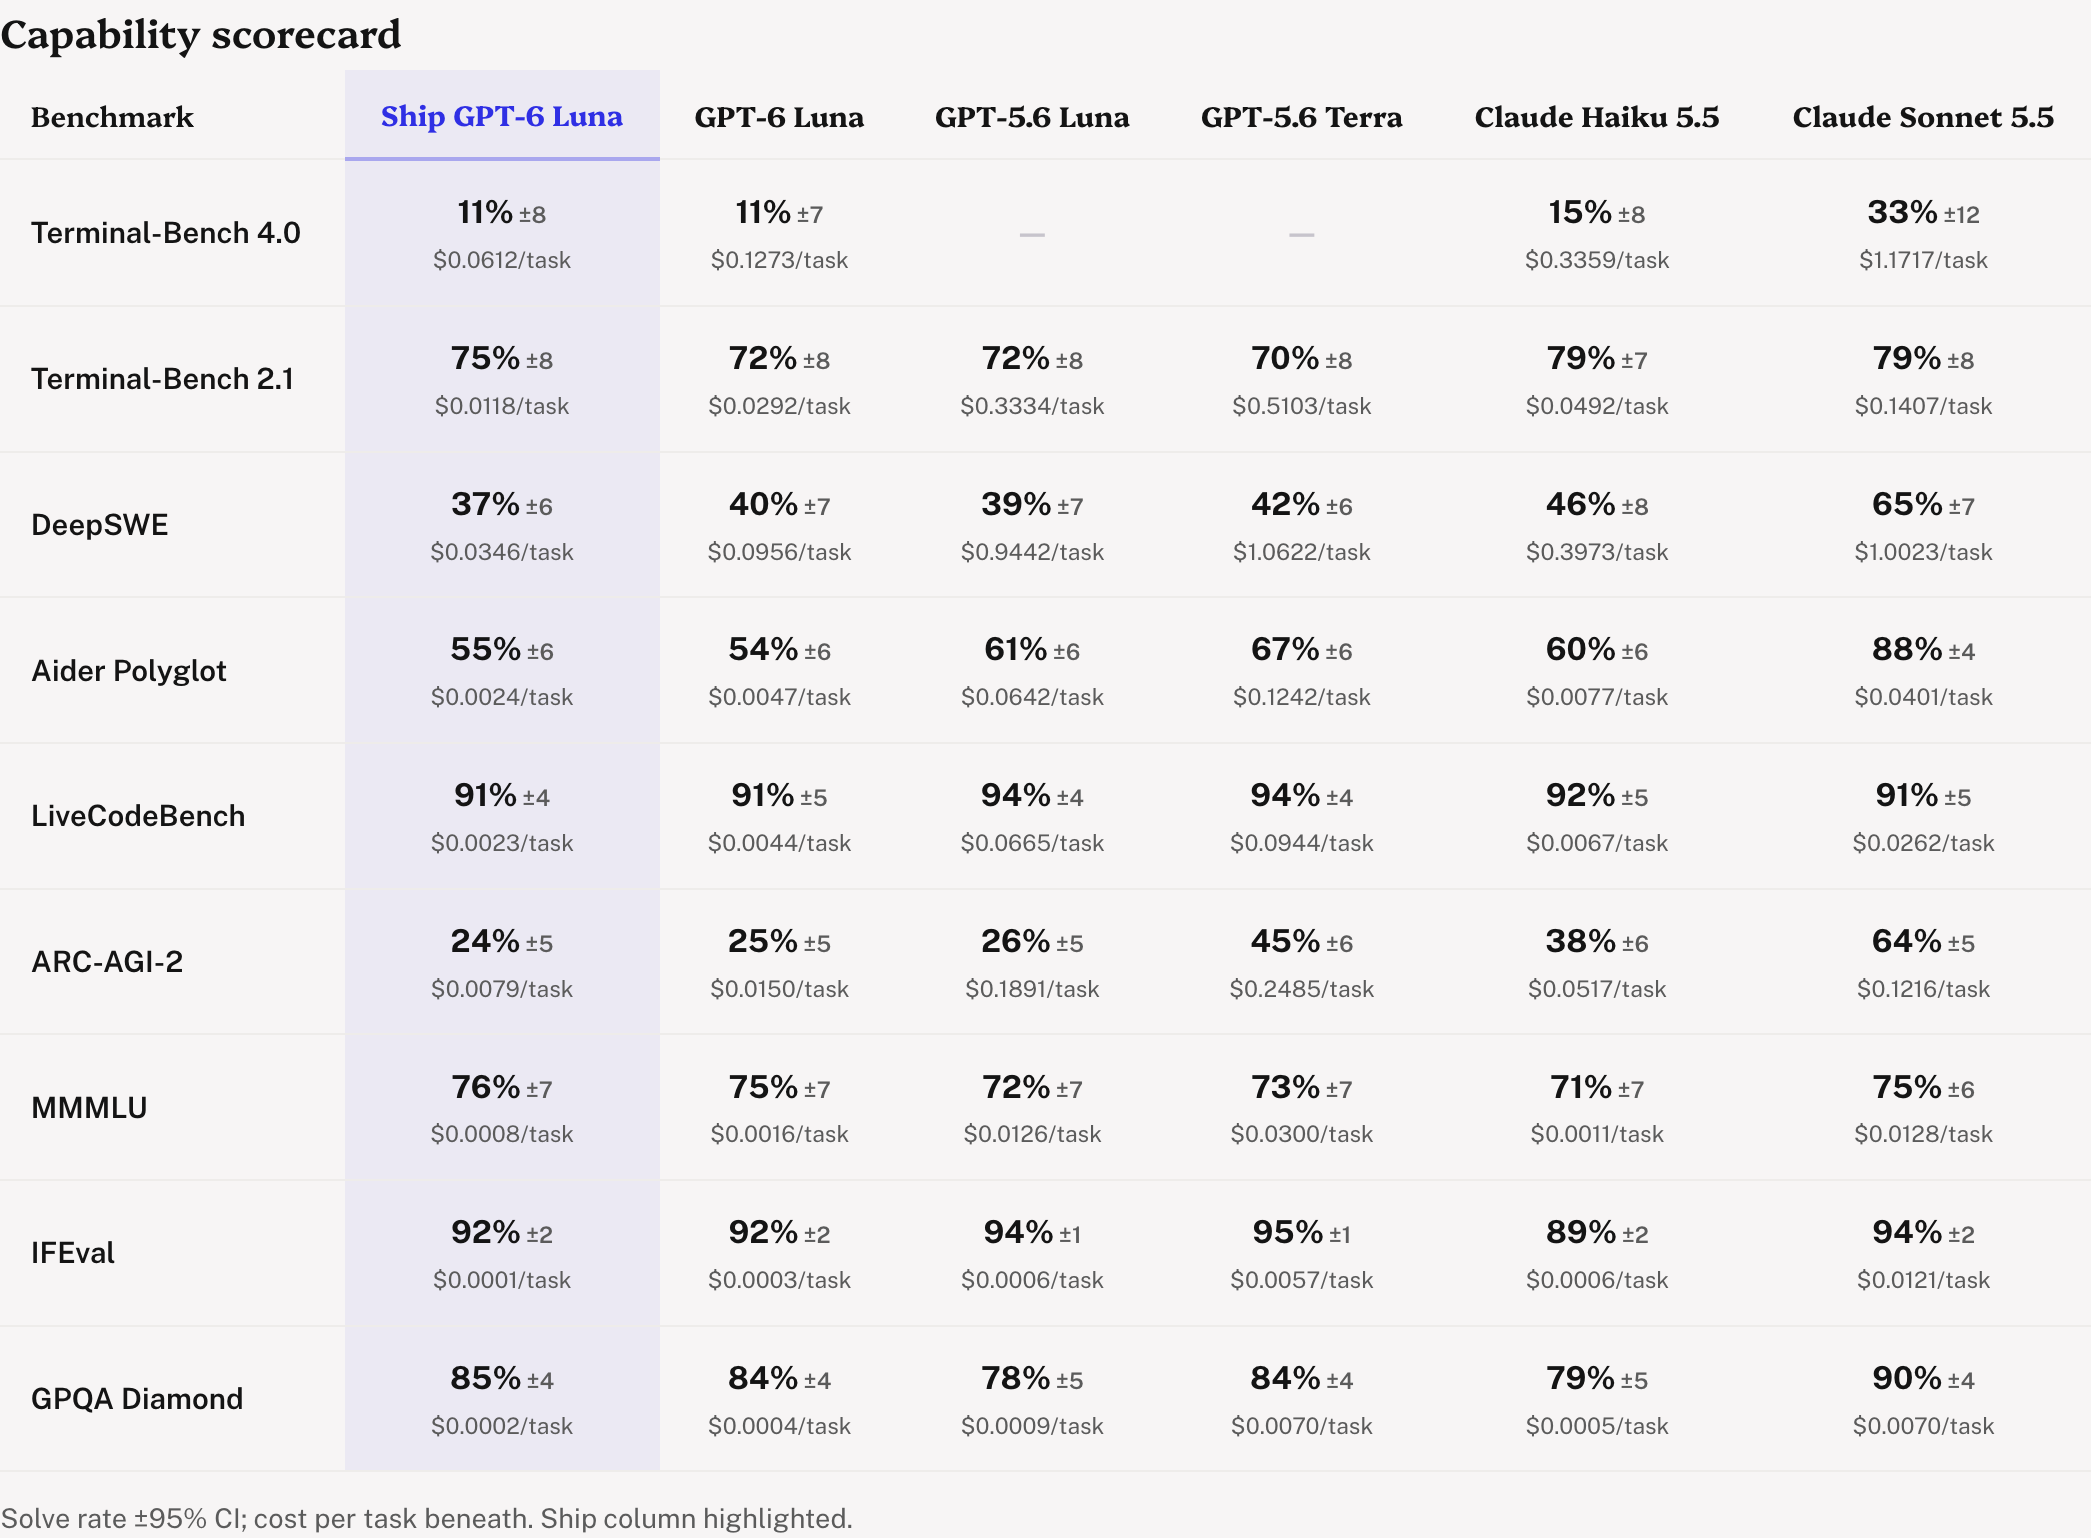
Capability equivalence
Across every public benchmark we tested, Ship lands inside its reference model's margin of error — at under half the cost per task.
Behavioral equivalence
A drop-in replacement has to act like the model it replaces, or you'd have to change your harness (prompts, parsers, tools, etc.). Here the traces show something different from our other grades: Ship GPT-6 Luna reaches comparable solve rates while doing measurably less work per task — fewer tool calls, shorter sessions, fewer tokens and lower wall latency, giving 60% distributional overlap rather than the 80-90% we see elsewhere. If your harness is tuned to GPT-6 Luna's step count or latency profile, test before switching.
The tool mix shifts with that lighter workload: Ship issues fewer bash calls per task rather than redistributing them, so a prompt tuned to GPT-6 Luna's tool habits should be re-checked on Ship rather than assumed to carry over.
The time budget keeps the same shape — most of it in model generation, the rest in tool execution — but Ship finishes a task in roughly half the wall time, so totals differ even where the split does not.
Step back to the whole trace and Ship's runs still cluster with GPT-6 Luna's, while GPT-5.6 Luna — a model with similar benchmark performance — sits clearly apart.
And it's task-for-task, not just on average. Bucket every task by how often GPT-6 Luna solves it, and Ship tracks it bucket-for-bucket far more tightly than any other model — the same hard tasks stay hard, the same easy ones stay easy.
Get started
This new ship model is available now. Swap one string: model="ship-like/gpt-6-luna"
Bring your private evals or production traffic and we'll compare Ship against your current model directly. Get an API key · Talk to us about an SLA.