

Claude Haiku 5.5
Ship gives you the highest intelligence per dollar of any frontier model by finding the cheapest execution that still meets a model's quality grade. We first introduced it for Claude Opus 4.8 and GPT 5.6 Sol. Today we're adding Claude Haiku 5.5 with the same quality SLA, the same cost reduction, and the same ease of use.
Just name a reference model as a quality grade, and we fulfill each request in the cheapest way that still meets that grade. We measure both Capability Equivalence and Behavioral Equivalence to the reference model, so that the model performs as well as expected, and it works the same way within your harness when you switch to ship.
TL;DR. Changemodel="anthropic/claude-haiku-5-5"tomodel="ship-like/claude-haiku-5-5". Same answers, same behavior, at 49.4% lower cost in our evals, with a quality SLA.
New to Ship? Start with Introducing Ship.
Capability equivalence
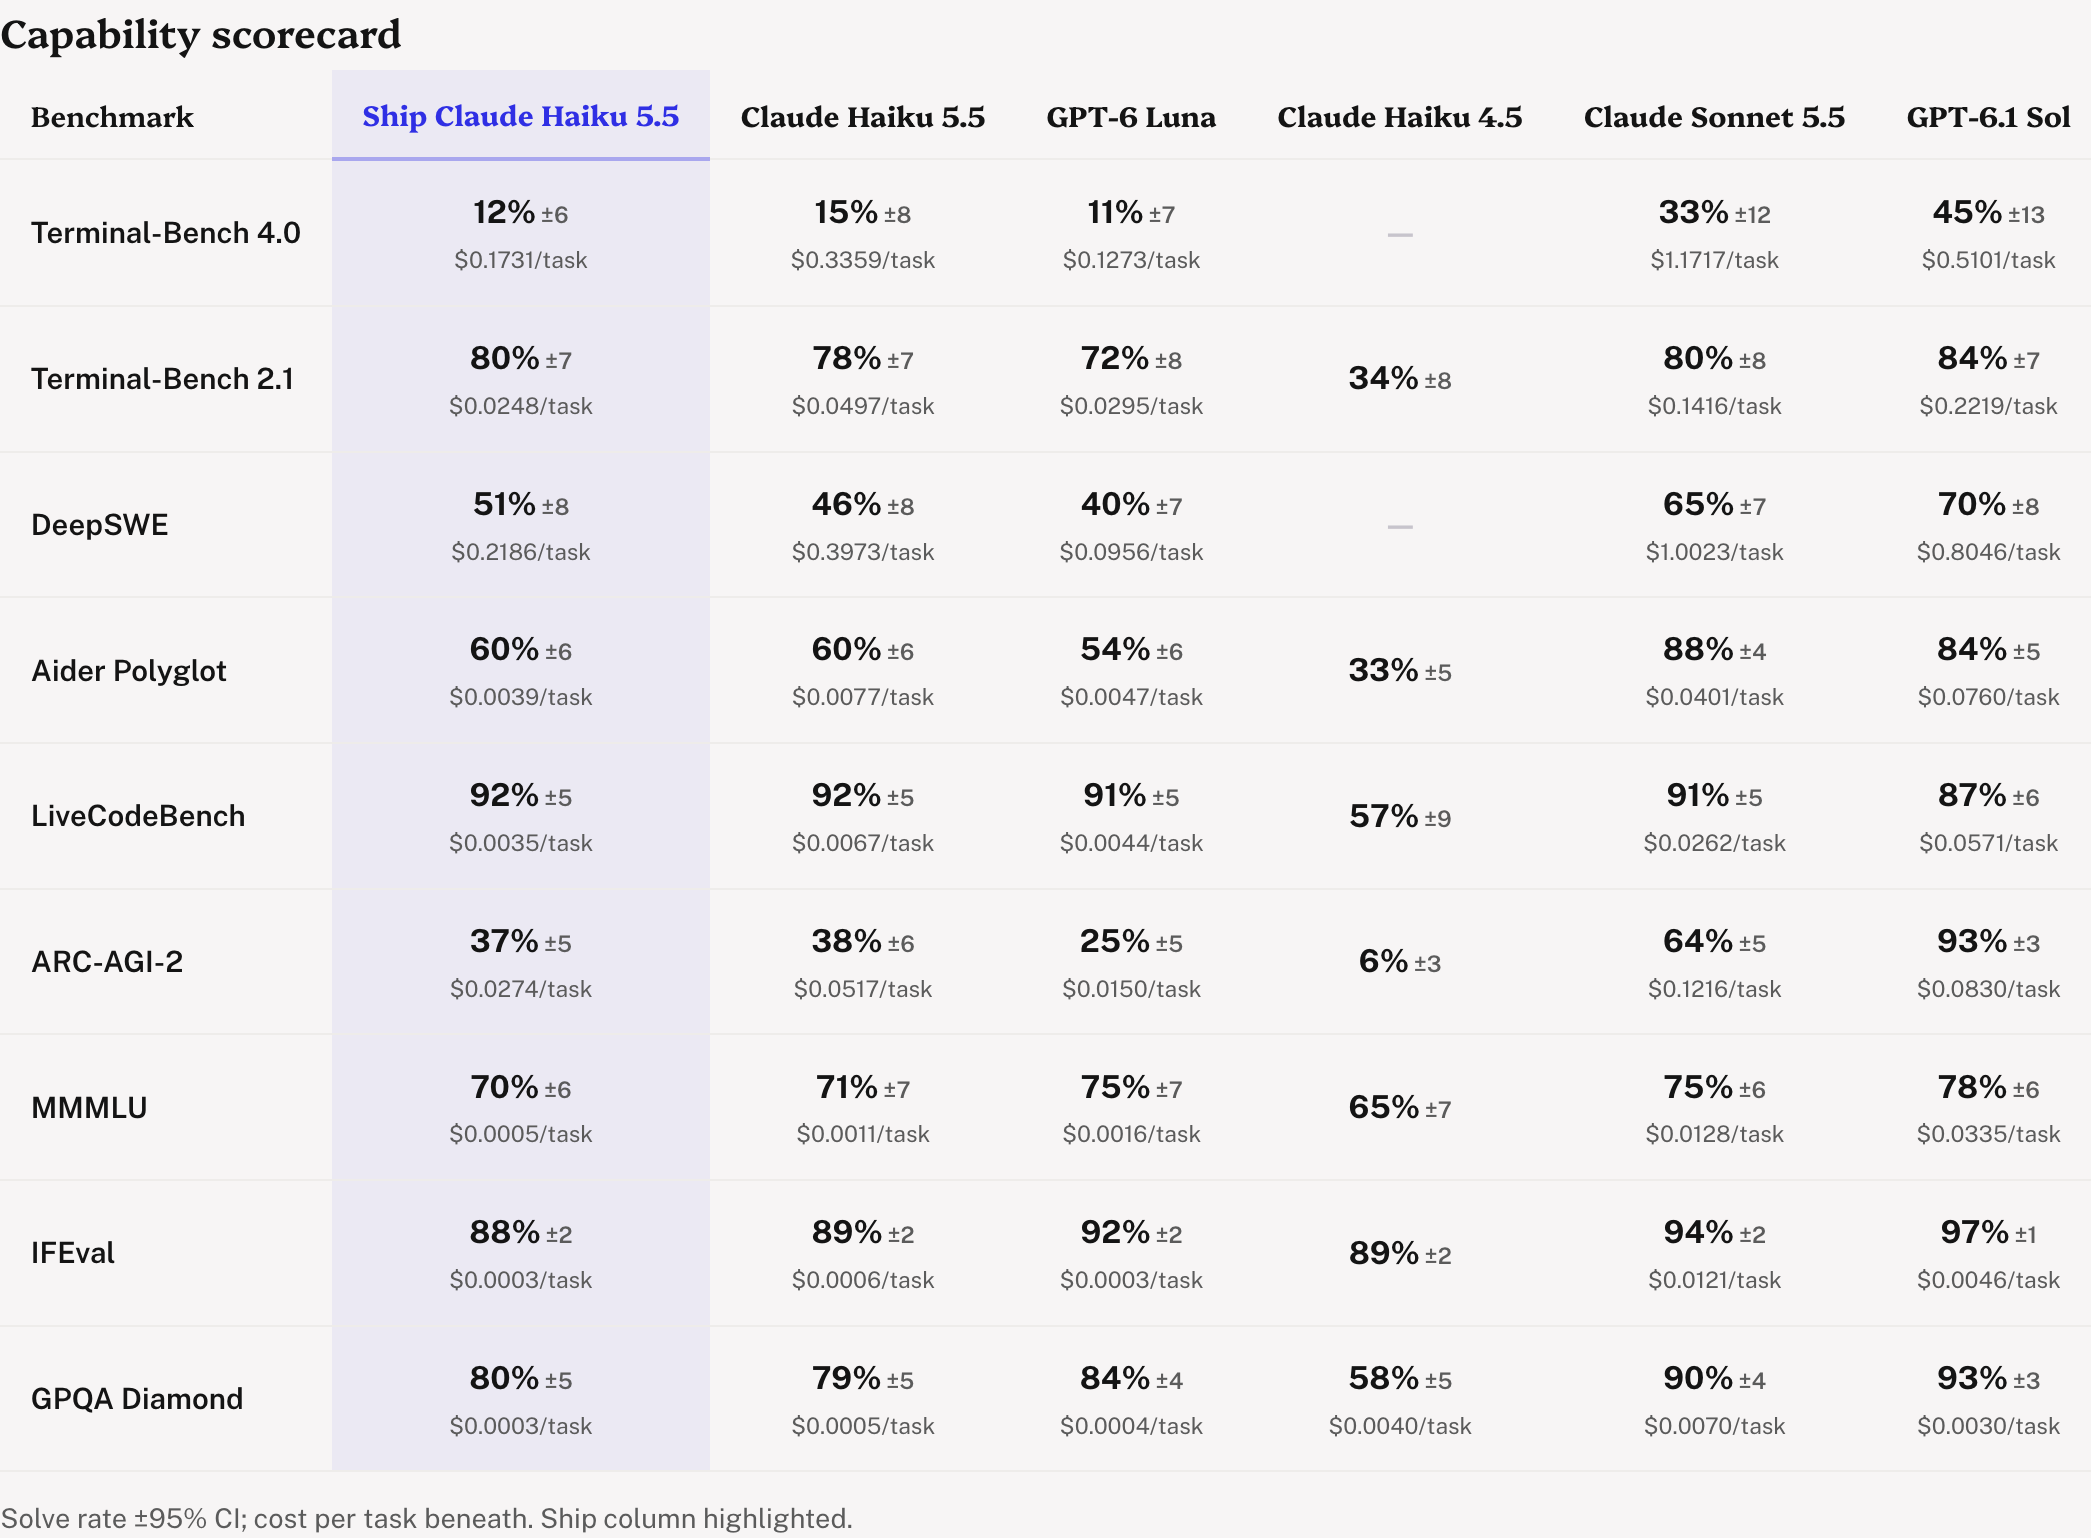
Across every public benchmark we tested, Ship lands inside its reference model's margin of error — at roughly half the cost per task.
Behavioral equivalence
A drop-in replacement has to act like the model it replaces, or you'd have to change your harness (prompts, parsers, tools, etc.). Claude Haiku 5.5's Ship grade has 90% distributional overlap with it across nine behavioral axes — eight of the nine agree to within 19%, including tool-call count, session length, output tokens and cache hit rate.
Zoom into tool use and the two grades reach for the same tools in close to the same proportions — read and bash shares land within 9% — so a prompt tuned to Claude Haiku 5.5's tool habits behaves the same on Ship. Ship does lean a little harder on edit operations.
The time budget splits the same way, too — most of it in model generation, the rest in tool execution — so the shape of the latency profile carries over, with Ship running about a fifth longer end to end.
Step back to the whole trace and the equivalence is holistic: embed each run and Ship lands inside Claude Haiku 5.5's cloud, while GPT-6 Luna — a model with similar benchmark performance — sits clearly apart.
And it's task-for-task, not just on average. Bucket every task by how often Claude Haiku 5.5 solves it, and Ship tracks it bucket-for-bucket far more tightly than any other model — the same hard tasks stay hard, the same easy ones stay easy.
Get started
This new ship model is available now. Swap one string: model="ship-like/claude-haiku-5-5"
Bring your private evals or production traffic and we'll compare Ship against your current model directly. Get an API key · Talk to us about an SLA.